NVIDIA GeForce RTX 5090 Founders Edition vs Mac Studio M5 Max for local AI
NVIDIA GeForce RTX 5090 Founders Edition should generate tokens faster (more memory bandwidth). Mac Studio M5 Max fits bigger models. Mac Studio M5 Max is cheaper right now by $5,401.
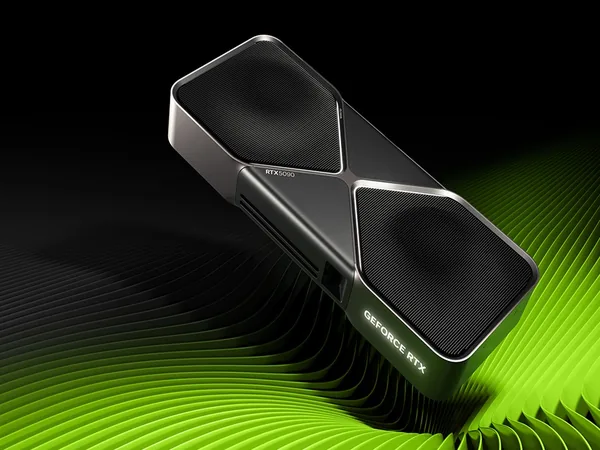
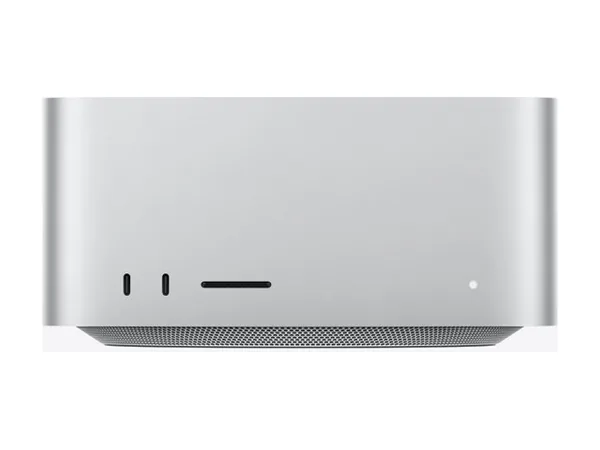
Specs
| NVIDIA GeForce RTX 5090 Founders Edition | Mac Studio M5 Max | |
|---|---|---|
| Stock | In stock | Available |
| Lowest price | $8,500 | $3,099 |
| Memory | 32 GB GDDR7 VRAM | 48 GB Unified memory |
| Usable for models (est.) | ~30 GB | ~36 GB |
| Bandwidth | 1,792 GB/s | 614 GB/s |
| Software | CUDA | MLX / Metal |
| Price per GB | $265.62 | $64.56 |
Model by model (4-bit)
| Model | NVIDIA GeForce RTX 5090 Founders Edition | Mac Studio M5 Max |
|---|---|---|
| Qwen3.5 9B | Fits~197 tok/s | Fits~68 tok/s |
| Gemma 4 12B | Fits~148 tok/s | Fits~51 tok/s |
| GPT-OSS 20B | Fits~562 tok/s | Fits~193 tok/s |
| Gemma 4 26B-A4B | Fits~467 tok/s | Fits~160 tok/s |
| Qwen3.8 27B | Fits~66 tok/s | Fits~23 tok/s |
| GLM-4.7-Flash 30B-A3B | Fits~591 tok/s | Fits~203 tok/s |
| Gemma 4 31B | Fits~57 tok/s | Fits~20 tok/s |
| Qwen3.6 35B-A3B | Fits~591 tok/s | Fits~203 tok/s |
| Llama 3.3 70B | Won't fit | Won't fit |
| Qwen3-Next 80B-A3B | Won't fit | Won't fit |
| Llama 4 Scout 109B-A17B | Won't fit | Won't fit |
| GPT-OSS 120B | Won't fit | Won't fit |
| Nemotron 3 Super 120B-A12B | Won't fit | Won't fit |
| Qwen3.5 122B-A10B | Won't fit | Won't fit |
| Qwen3 235B-A22B | Won't fit | Won't fit |
| Muse Spark Open 816B-A42B | Won't fit | Won't fit |